Better training data usually beats a bigger model. AI embeddings are one of the cheaper ways to get there: they lift data quality and cut down how much hand-labeling your team has to sit through. Once messy input has been turned into something a machine can actually read, the downstream work gets faster, the manual steps thin out, and whole workflows start to look different.
Machine learning has a real shot at reshaping how we live and work. But the model is only ever as good as what you fed it. Ask anyone who has shipped one: the quality of the training data does more for accuracy and reliability than almost any architectural choice you make afterward.
So this post looks at why good training data matters so much, and how embedding in machine learning makes it better. First, though, the basics. What are embeddings in machine learning, really?
What is an Embedding in Machine Learning?
Machine learning (ML) is a particular way of writing programs: you hand them raw data and they turn it into something useful for a specific job. Nobody writes the rules by hand. The algorithm picks patterns out of the data itself, which opens the door to analysis and prediction that hand-written logic could never reach.
Picture an ML system watching sensor readings on a factory floor, flagging a machine that is about to fail, running on an embedded system the size of a deck of cards. Or one that hears a spoken command in raw audio and switches on a light. With ordinary software, a developer sits down and spells out the rules. With machine learning in embedded systems, the system works those rules out for itself while it trains.
Traditional programming goes like this: a developer writes an algorithm, the algorithm takes input, applies rules somebody decided in advance, and returns an output. Fine for tidy problems. Water boils at 100°C at sea level, so you can hard-code that. Now try predicting a machine breakdown, where temperature and vibration and half a dozen other readings all pull on each other at once. Writing those rules by hand gets ugly fast.
The ML route is different. Engineers collect a lot of training data and pour it into algorithms built to spot patterns, and the system derives the prediction rules on its own. That pays off especially well in embedded systems, where embeddings in machine learning can map tangled relationships between data points and forecast outcomes without anybody writing a rule sheet.
What comes out of that training phase is a model. Feed it fresh data and it infers a prediction. That step, usually called embeddings mapping, is where most of the accuracy in machine learning in embedded systems is won or lost.
The Significance of High-Quality Training Data
Training data quality feeds straight into how precise and dependable your model turns out to be. A model that spots real patterns and predicts well has been fed a lot of data that was varied, correct, and not skewed toward any one slice of the world. Feed it errors and bias instead, and it hands you back errors and bias, dressed up as a prediction.
This is not only a small-model problem. It applies to Foundation Models too, ChatGPT and Google’s BERT included. The Washington Post ran a detailed analysis of the giant datasets behind some of the most powerful large language models (LLMs). They dug into Google’s C4 dataset in particular, and the takeaway was that volume alone does not carry you when you are training LLMs, quality has to come with it. Vector embeddings do a lot of the work here, turning sprawling datasets into something a model can actually chew on.
Take image recognition. If half your training images carry wrong or half-finished labels, the model will stumble on similar images later and classify them badly. An embedding layer softens that problem, giving the model a better handle on messy inputs, whether those are images, text, or something else entirely.
And bias compounds. If the training data leans toward certain groups or demographics, the model learns that lean and repeats it, which is how you end up with unfair or outright discriminatory output. Embedding examples drawn from skewed data will happily carry that prejudice forward. Google’s Vision AI model produced racist results because of bias in what it was trained on. Curating and validating your dataset is not a box-ticking step, it is the step.
Related: Comparison of Large Language Models
What is Vector Embedding in Machine Learning?
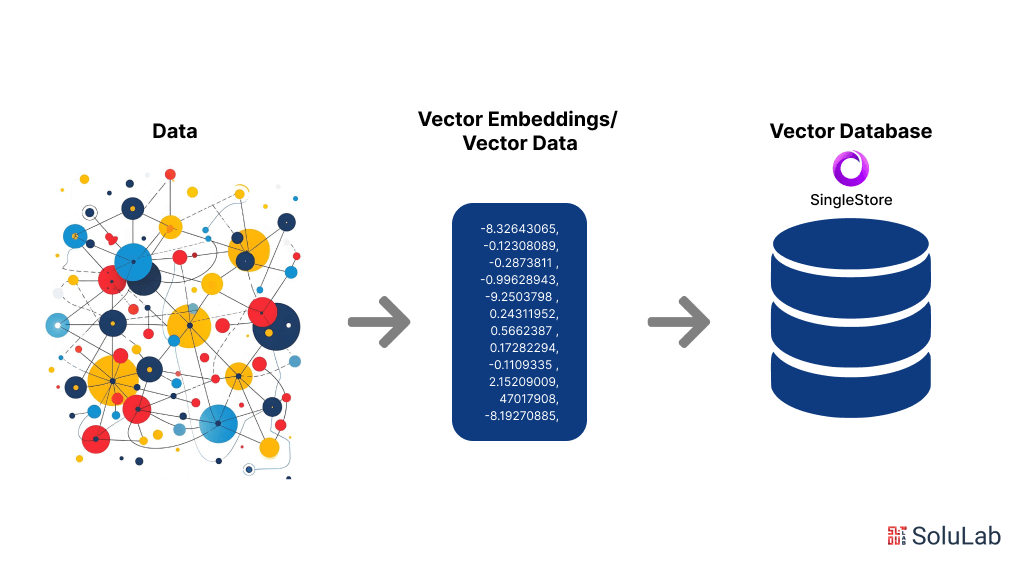
Vector embeddings sit near the foundation of machine learning, and they matter most in natural language processing (NLP) and computer vision. The idea: take data a model cannot read, a word or an image, and turn it into a numerical vector it can. Those vectors hold onto the semantic relationships and patterns hiding in the original data, which is what lets a model make sense of anything and predict from it.
An embedding model is what produces those vectors. It learns from large datasets, takes raw input such as words or full sentences, and compresses each one into a dense, lower-dimensional vector. The aim is geometric: words that mean related things should land near each other in the vector space. Get that right and the model generalizes better, catching patterns across inputs it has never seen in exactly that form.
Inside a neural network, the embedding layer does the conversion. It takes discrete things, words or tokens, and turns them into continuous vectors the rest of the network can work with. For NLP that covers a lot of ground: text classification, machine translation, sentiment analysis.
Push the same idea up a level and you get sentence embedding, where whole sentences become vectors. Now the model can do things word-level vectors cannot: judge whether two sentences mean the same thing, summarize text, run a semantic search. Context stops being invisible.
Put simply: vector embeddings, embedding models, the embedding layer, and sentence embedding are what let an ML system deal with complicated data at all.
How Do Embeddings Work?
Embeddings turn categorical or textual data into numbers a model can read. That is the whole job, and it is why they show up everywhere in machine learning and NLP. Without that step, a model has no way to learn relationships in the data, whether those are words sitting next to each other in a sentence or features describing an object. Here is how the pieces fit together, section by section.
What is Text Embedding in Machine Learning?
Text embedding converts text into fixed-length vectors. Those vectors, the embeddings, carry the meaning of the text with them. Every word or phrase becomes a point in a multi-dimensional space, and words that mean similar things end up near neighbors. That geometry is what gives a model any grip on context.
“King” and “queen” tend to sit close, because they turn up in similar company. “Banana” and “computer” do not. That is the whole intuition. What is text embedding in machine learning comes down to turning raw text into vectors a model can process, which is what makes sentiment analysis, translation, and text generation possible in the first place.
Embedding in NLP
Embedding in NLP (Natural Language Processing) carries almost any task that involves reading or processing text. Words and whole sentences become numbers, and from those numbers the model works out how words relate to each other and what they mean. Structure, meaning, context: embeddings are how all three reach the model.
Sentiment analysis is the easy example. A model reads customer reviews, turns each word into a vector, and sorting positive from negative from neutral gets much simpler. The same machinery shows up in machine translation, question answering, and speech recognition. Linguistic features and the relationships between words get captured in a form the model can use, and no NLP task works without that.
Feature Embedding in Machine Learning
Feature embedding in machine learning is not limited to text. Images, categorical data, audio: all of it qualifies. The premise stays constant. Take complicated, high-dimensional input features and squeeze them into a low-dimensional space without losing how the features relate to each other.
Recommendation systems make this concrete. Users and products both become vectors in the same space. The closer a user’s vector sits to a product’s, the likelier that user wants that product. You have cut the dimensionality of the input and kept the relationships that mattered, and the model gets faster and more accurate for it.
How Vector Embeddings Are Learned?
Vector embeddings get learned while the model trains. They start out random, or seeded from pre-trained values, and then the loss function nudges them on every pass. Over many passes they drift toward a better representation of the input, and the predictions improve with them.
Often you do not start from zero at all. Word2Vec, GloVe, BERT: these pre-trained models have already absorbed enormous amounts of text and built solid embeddings from it, and you fine-tune them on your task. You inherit relationships and patterns somebody else paid to learn, and apply them to a new dataset.
The Role of the Embedding Layer in Neural Networks
The embedding layer carries a lot of weight in deep learning models, particularly in NLP applications. Its job is narrow and specific: take the input, words or tokens, and turn it into embeddings. In an NLP model it is usually the very first layer, converting each word into a vector before anything else touches it.
In a text classifier, for example, the embedding layer swallows raw sentences and hands out vectors. Convolutional or recurrent layers take it from there and eventually produce a prediction. That first conversion is what lets everything downstream find the complicated relationships buried in the data.
Sentence Embedding for Contextual Understanding
Word embeddings earn their keep. But sentence embedding goes further, representing entire sentences or paragraphs as single vectors, which lets the model hold onto harder relationships, including the context a word showed up in.
Translation shows the difference. A model working with sentence embedding grasps what the sentence means as a whole, not just what each word means on its own, so the translation keeps the intent and the tone of the original instead of flattening both. Sentence embedding models such as BERT and GPT are the ones doing this in most modern NLP systems, producing embeddings that reflect the whole context of the input.
Between vector embeddings, embedding models, and embedding layers, ML systems get a workable way to learn from large, complicated datasets. Text, images, whatever else you have: embeddings shrink the dimensions, lift performance, and keep the relationships that actually carry signal.
What Are Embedding Models?
Embedding models are the algorithms that take complicated, high-dimensional data and compress it into dense representations, the embeddings, sitting in a multi-dimensional space. That compression is what gives an ML system a chance at reading intricate patterns. Choose the right embedding models and a data scientist can get real inferences out of data that would otherwise be unusable. A few of the common ones follow.
1. Principal Component Analysis (PCA)
PCA is the old reliable of dimensionality reduction, squeezing complicated datasets down into lower-dimensional vectors. It finds the patterns and similarities between data points and compresses them into embedding vectors that hold the gist of the original. There is a cost. Dropping dimensions means dropping information, so some of it goes missing in the compression. Still, for visualizing and simplifying a big dataset, PCA remains hard to beat.
2. Singular Value Decomposition (SVD)
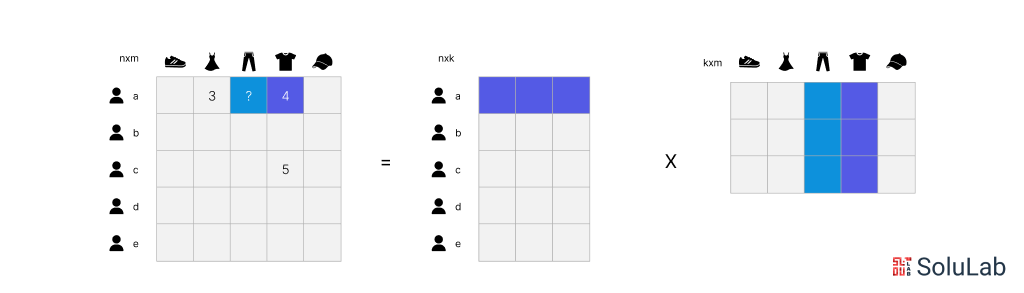
SVD is a different kind of embedding model: it splits a matrix into its singular matrices. Those singular matrices hold onto the information that mattered in the original, which gives ML models a better read on the semantic relationships inside the data. You see SVD in image compression, text classification, and recommendation systems, anywhere keeping the most relevant features is enough. Embeddings mapping in SVD puts the data into a shape that makes those jobs simpler.
3. Word2Vec
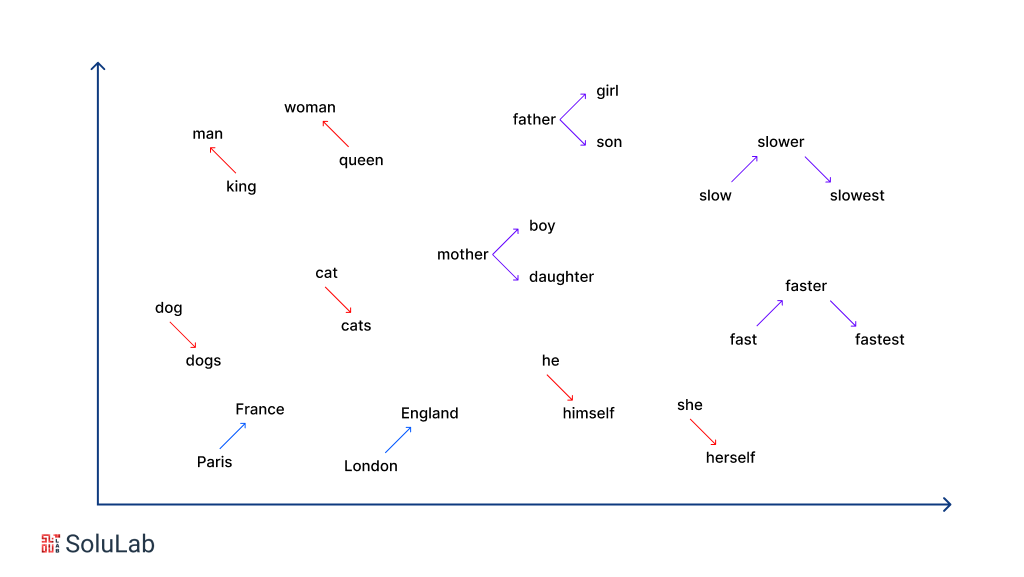
Word2Vec builds word embeddings by connecting words through the contexts they appear in and the meanings they share. Data scientists train Word2Vec on huge piles of text so the model can pick up natural language. Each word becomes a point in the embedding space, and words with similar meanings cluster. Two flavors exist: Continuous Bag of Words (CBOW) and Skip-gram. CBOW guesses a word from the words around it. Skip-gram runs the other direction, guessing the surrounding context from one word. It works well, but it has a blind spot, and it is a known one: a word with several meanings gets a single vector, so the different senses blur together.
4. BERT
BERT (Bidirectional Encoder Representations from Transformers) is a transformer-based language model built to read language closer to the way a person does. Like Word2Vec, it produces word embeddings from the input. Unlike Word2Vec, it tells apart the different senses a word can carry, even when the spelling is identical. BERT will give you separate embedding examples for “play” in “I went to a play” and “play” in “I like to play.” That context-awareness is exactly why BERT does so well at text classification, question answering, and translation.
5. Knowledge Graph Embedding Model
A knowledge graph embedding model takes the entities and relationships out of a knowledge graph and drops them into a low-dimensional vector space. Once they are there, an ML system can infer how two entities relate simply by looking at where they sit relative to each other. That turns the structured, information-dense contents of a graph into something a model can reason over, which is what powers recommendation, entity resolution, and semantic search. Embeddings mapping is the piece doing the translation from tangled graph relationships into something efficient to compute with.
How to Create High-Quality Training Data Using Embeddings?
Good training data is the difference between a model that works and one that looks like it works. Feature embedding in machine learning is one of the strongest tools you have for getting there, because it turns raw data into dense, informative representations the learner can actually use. Here is how to put machine learning embedding techniques to work on your training data.
1. Embedding Features for Better Data Representation
Big datasets tend to arrive with features that are either enormously wide or mostly empty, and both hurt performance. Feature embedding in machine learning collapses those high-dimensional features into compact, dense vectors, the vector embeddings. What survives the collapse is the relationships between data points, which is exactly what the model needs to learn a pattern. In practice this is where categorical variables and text data stop being a headache: both drop neatly into a continuous space that means something.
2. Ensuring Consistent and Informative Data in Embedded Systems
On embedded systems you are fighting for every cycle and every kilobyte, so embedding techniques stop being optional. Cutting dimensionality with machine learning embedding keeps the training data good while keeping the footprint small. The data gets easier to move around, and the parts that carried information stay intact, so predictions hold up even when the hardware barely has room to breathe.
3. Using Vector Embeddings for Text and Categorical Data
Embedding text is the everyday case, especially for NLP work. Vector embeddings such as Word2Vec or GloVe give you words and phrases as dense vectors in a continuous space, with the semantic relationships between them intact. One caveat that trips teams up: if the dataset you build these from is small or narrow, the vectors come out thin and the model inherits that thinness. Use something large and varied. Do that and language understanding improves noticeably, which shows up directly in sentiment analysis, text classification, and translation.
4. Enhancing Data Consistency and Accuracy with Embeddings
Embeddings also clean things up. Turn features into vector embeddings and similar data points gather in the same neighborhood, which makes an outlier or an inconsistent entry stand out instead of hiding. Spot it, drop it. What is left is training data the model can trust.
5. Cross-Domain Embedding for Versatile Training Data
Working across domains, or across data types, embeddings can bring everything under one roof. Pair visual data with the text describing it through joint machine learning embedding techniques and both land in the same vector space. That multi-modal setup gives the model more than one angle on the same problem, and accuracy tends to follow.
So: feature embedding in machine learning and vector embeddings are how you get training data that is structured, informative, and worth the compute. On a tiny embedded board or across a large-scale AI models, the technique is the same, and so is the payoff. The model understands complicated, high-dimensional data instead of drowning in it.
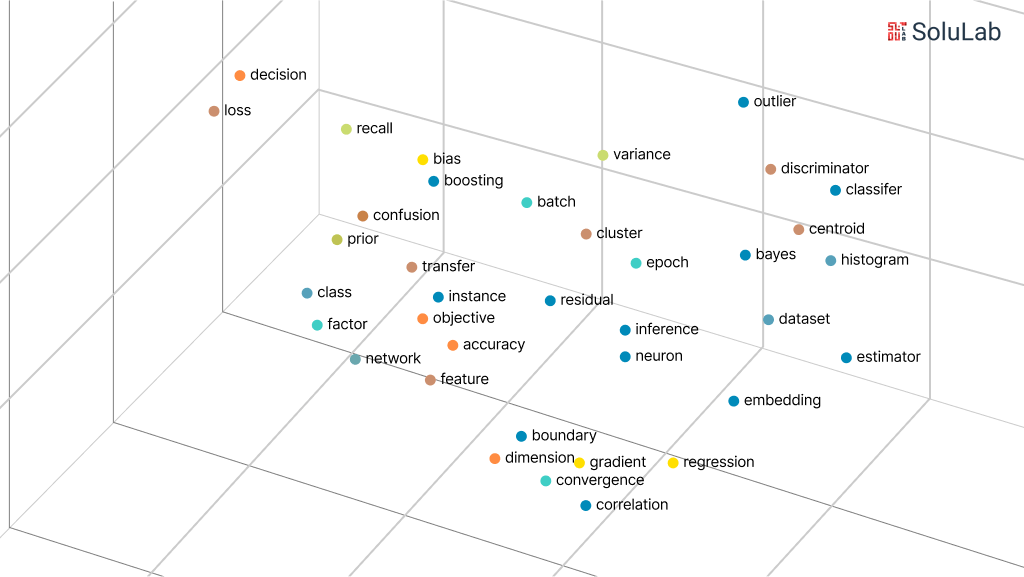
Best Practices for Embeddings in Computer Vision & Machine Learning
Embeddings do heavy lifting for AI and ML in data integration, computer vision and machine learning most of all. Used well, they take high-dimensional data and produce vector spaces that are both manageable and meaningful, and both model performance and generalization improve. Used carelessly, they quietly cost you accuracy. A few practices worth keeping.
1. Start From Pretrained Models for Efficient Embedding
For vision work, pulling embeddings out of a pre-trained model such as ResNet or EfficientNet can cut your training time dramatically. Those models have already done their reading on vast datasets, and their learned representations transfer to your task. This matters most around AI and ML in data integration, where the job is lining up and reconciling data arriving from different sources and in different shapes.
2. Fine-Tune Embeddings for Domain-Specific Tasks
A pre-trained model gets you a floor, not a ceiling. Fine-tune the embedding layers on your own domain and the results usually improve. Building credit risk models with machine learning? Tune the embeddings on financial records and customer behavior, and they start catching the quirks that only exist in that data. Risk assessments get sharper as a result.
3. Apply Dimensionality Reduction Techniques
Vision data is wide, and wide data is expensive to compute on. Dimensionality reduction with PCA (Principal Component Analysis) or t-SNE trims the embeddings down while keeping what mattered. That trade is especially worth making when you are building MLOps consulting services, where performance and resource efficiency both have to hold.
4. Regularize Embedding Layers to Prevent Overfitting
An embedding layer can carry millions of parameters, and every one of them is another chance to overfit. Regularize. L2 normalization or dropout on the embedding layers will do it. Skip this step in a fraud detection system or in credit risk models with machine learning, and the model will look excellent in training and fall apart on real cases.
5. Evaluate Embeddings with Visualization Tools
Look at your embeddings before you trust them. Tools like t-SNE or UMAP will show you how the data points cluster in the embedding space, and clusters that make no sense to your eye are usually a warning. That visual check tells you whether the embeddings caught the patterns and similarities you expected, which matters a great deal on MLOps consulting services, where knowing why a model behaves as it does decides whether it ships.
6. Test Embeddings Across Different Models
And test them against more than one architecture. Embeddings that shine inside a convolutional neural network doing image classification can behave quite differently once a transformer gets hold of them. On AI and ML in data integration projects, running that comparison is how you find out whether your embeddings travel well or only work in the one place you built them.
Follow those and you end up with models that are cheaper to run and easier to trust, in vision work and in wider machine learning applications like credit risk models with machine learning.
How SoluLab Can Help With Embedding in Machine Learning?
SoluLab works as an AI development company, and embedding in machine learning is squarely in what we build. Our team puts together embedding models shaped around what you actually need, whether that is NLP, computer vision, or other AI-driven applications. We know vector spaces, feature embeddings, and dimensionality reduction well enough to build something that scales, so your models pick up the complicated patterns in your data instead of skating past them.
We have done this in finance, in healthcare, and in plenty of places between, putting machine learning in embedded systemsfor decisions that land faster and hold up better. Need embedding layersbuilt for a new AI model, or a tune-up on the machine learning algorithms you already run? We stay on it end to end. Have a project in mind? Contact us and tell us what you are trying to build.
FAQs
Shipra Garg is a tech-focused content strategist and copywriter specializing in Web3, blockchain, and artificial intelligence. She has worked with startups and enterprise teams to craft high-conversion content that bridges deep tech with business impact. Her work translates complex innovations into clear, credible, and engaging narratives that drive growth and build trust in emerging tech markets.