

Something changed in computer vision, and it happened faster than most teams planned for. Models built to read pictures stopped behaving like narrow, single-purpose tools. They got enormous. They got trained on data at a scale that would have sounded absurd a decade ago. And now they sit quietly inside radiology software, factory inspection rigs, checkout counters, and tractors, doing work that used to require a trained human eye.
This piece covers what large vision models actually are, why their size matters as much as it does, and where they earn their keep. We will get into architecture and parameter counts, because that is where the interesting differences live.
Healthcare. Manufacturing. Finance. Entertainment. The list of sectors that depend on these systems keeps stretching, and the pattern is consistent: decisions get faster, repetitive visual work gets handed off, and the humans move up a level. How we see machines seeing has changed the work itself.
Stick with us through the sections below. We walk the use cases, the architecture quirks, the places where projects stall, and where the research is pointing next. One thing worth saying early: automation is the least interesting part of this story. The interesting part is what teams build once visual grunt work stops being the bottleneck.
What are Large Vision Models?
A large vision model is an artificial intelligence (AI) system built to process and interpret visual information. Deep learning underneath, trained on huge datasets, tuned until it can read what it is looking at. The word “large” is doing real work in that name. It points at parameter count, and parameter count is usually what separates one of these models from an older approach that looks superficially similar.
They belong to the broader family of artificial neural networks, but with a narrow specialty: computer vision tasks. Computer vision models let machines interpret images and video, then act on what they find.
Use Cases Of Large Vision Models in Various Industries
The use cases spread across a wide range of industries, and each one takes something slightly different from what these models offer.
Healthcare
In healthcare, the gain shows up in diagnostic accuracy. A model reads the scan, flags the anomaly, and sometimes projects how a condition is likely to progress. It does not replace the clinician. It gives the clinician a second read before the decision gets made, which is where better patient outcomes and more specific treatment plans tend to come from.
Read Blog: AI Agents in Healthcare
Automotive
Autonomous vehicles run on this. Sensors pour in visual data, the model reads it, and the car figures out where it is, what is around it, and what to do in the next fraction of a second. Object recognition, positioning, real-time calls. Road safety improves as a direct result, and the whole self-driving effort depends on the reading being right.
Manufacturing
On a production line, the job is quality control. Defects get caught fast, before a bad batch travels any further down the belt. There is a second payoff too: a model watching the line all day produces a running read on how the process itself is behaving, which is how teams find the slow leaks in throughput.
Related: Generative AI in the Manufacturing
Retail
Retailers put large vision models, or computer vision in retail, to work on customer analytics. The models read behavior, preference, and demographic signals out of visual data, and marketing teams turn that into targeted campaigns and a shopping experience that feels less generic. Inventory gets the same treatment. Stock levels stay closer to where they should be, and shrinkage drops.
Agriculture
Precision farming is one of the quieter success stories. Drones and satellites collect imagery, the model reads crop health out of it, projects yield, and spots pests or disease while there is still time to act. Farming decisions that used to rest on experience and a walk through the field now rest on both that and the data. Yields go up. So does sustainability.
- Entertainment
Recommendation engines are the obvious one. The model watches how you interact with visual content and shapes what comes next, which is how platforms keep people watching. Less obvious, and arguably more useful to the people doing the work: automated video and image editing, which cuts a large chunk out of the production grind.
Security and Surveillance
Detection and tracking are what these models are good at, so security was always going to be a natural fit. Public spaces, critical infrastructure, anywhere with more camera feeds than people to watch them. Spotting the thing that does not belong is the whole job, and doing it before something happens rather than after is the difference that matters.
Finance
Fraud detection leans on the same pattern-reading ability. The model looks at visual data, finds the thing that breaks the pattern, and flags it before the loss lands. Document work is the other half. Verification and data extraction used to be somebody’s entire afternoon, and now a good chunk of it runs unattended.
Read Also: AI in Finance
- Education
Education uses them for grading and assessment of visual work. Student submissions get read, feedback comes back quickly, and it comes back consistent, which is harder for a tired human marker than anyone likes to admit. Adaptive learning platforms take it further, adjusting what a student sees next based on how they handled what came before.
Strip away the sector labels and the value is the same everywhere: more accuracy, less time spent, and room to try things that were not practical before. That is what is changing how businesses run and what they can offer.
Examples of Large Vision Models (LVMs)
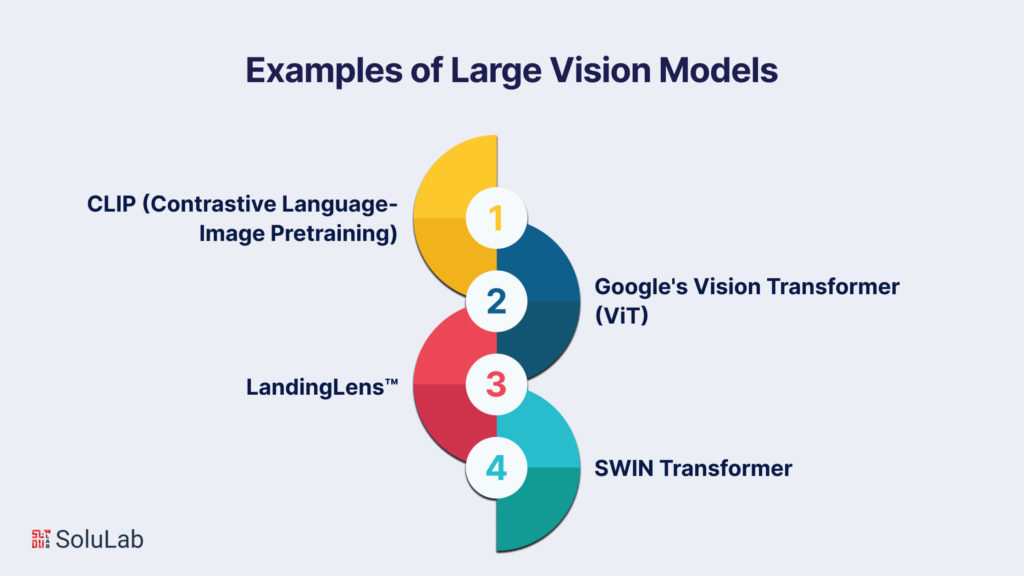
Here are a few of the names you will run into, and what each one is actually for:
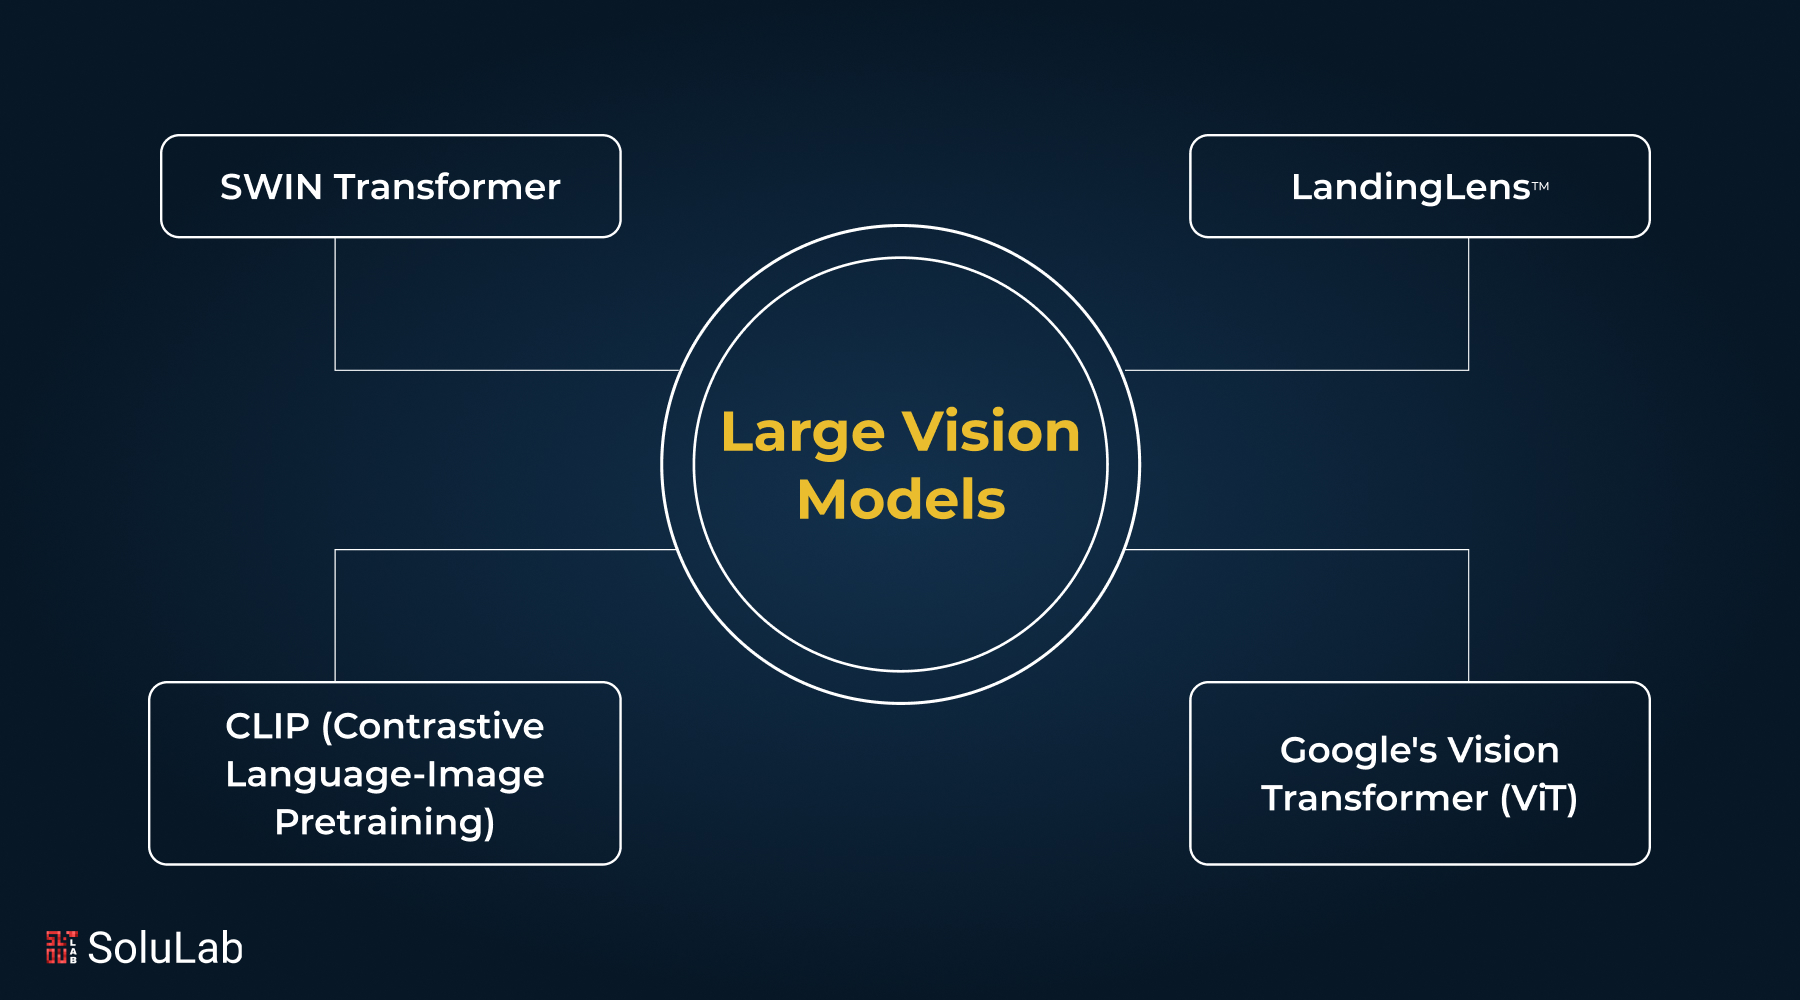
- CLIP (Contrastive Language-Image Pretraining): Built by OpenAI. CLIP was trained to read images and natural language together rather than separately, which was the interesting bit at the time. You see it behind image captioning, visual question answering, and image retrieval.
- Google’s Vision Transformer (ViT): ViT for short. Google built it for image classification using a Transformer-style architecture that chews on patches of an image rather than the whole thing at once. It posted state-of-the-art numbers across a run of classification benchmarks, and the approach stuck.
- LandingLens™: LandingAI’s platform, aimed squarely at people who cannot write code. Image labeling, model training, deployment to cloud or edge, all through an interface rather than a terminal. It opens computer vision work to a much wider set of users.
- SWIN Transformer: SWIN takes a hierarchical approach to visual recognition, building representations at multiple levels rather than one. It has done well on both image classification and object detection, which says something about how well the design handles messy, complicated scenes.
Look at those four together and you can see the range: bridging language and images, sharpening classification, and putting computer vision work within reach of people who are not machine learning engineers.
Distinctive Features of Large Vision Models: Parameters and Scale
What sets these models apart from everything else in AI? Mostly scale. Parameter count is the headline number, and it is not a vanity metric. Size and complexity are directly tied to what these systems can do and how widely they can be applied, so it is worth understanding what the number represents.
Parameters: The Driving Force Behind Large Vision Models
- Unprecedented Scale: The parameter counts dwarf what came before. Parameters are the internal variables the model tunes while it trains, and having a lot of them is what lets it pick up fine patterns and small distinctions in visual data that a smaller model simply flattens out.
- Deep Architectures: Deep neural networks, many layers of interconnected nodes. That depth matters because it lets the model learn in tiers: edges and textures at the bottom, abstract concepts higher up. Take the layers away and the understanding gets shallow in exactly the way you would expect.
- Learned Representations: A wide parameter space gives the model room to learn varied, detailed representations of what it sees. For image recognition that is the whole game. Subtle variations get caught rather than smoothed over, and accuracy holds up on data the model has not seen before.
- Transfer Learning Capabilities: This is the practical one. Take a model pre-trained on an enormous dataset, fine-tune it on a much smaller task-specific set, and you get something usable without the original training bill. That is how the same base model ends up in medical image analysis and industrial quality control.
Scale: Beyond the Numbers
- Massive Datasets: These models need enormous, varied training sets, and the variety matters as much as the volume. A model that has seen a wide spread of visual situations generalizes to new ones. A model trained on a narrow slice falls over the moment reality looks slightly different from the training data.
- Computational Intensity: Training is expensive. Not mildly expensive, either. You need serious hardware acceleration, GPUs or TPUs, running for a long time. The size of that compute bill is a fair proxy for how complex the model is and how much learning is actually happening inside it.
- Real-Time Inference Challenges: Training happens in a datacenter with money behind it. Inference often happens on a device bolted to a wall. That gap is where a lot of projects get stuck, and optimizing a large model for edge deployment turns into its own engineering effort rather than a final checkbox.
- Interconnectedness of Parameters: Parameters in Large Image Models are densely wired together, and that wiring is what lets the model pick up relationships between things rather than just cataloguing them one at a time. Object detection, segmentation, and scene understanding all depend on it.
So: scale and parameters, and the two are inseparable. Models of this size represent about as far as the current generation of hardware and technique will carry us, and the accuracy and depth they reach on visual tasks is the return on that investment.
Key Capabilities of Large Vision Models
Wide architectures and heavy training buy you more than image analysis. Here is what these models can actually do, one capability at a time.
Image Recognition
Recognition is the foundation. Identify what is in the picture, put it in a category, move on. Training on huge datasets gives these models a read on patterns, shapes, and features that older image processing techniques could not match, and the accuracy gap is not close.
- Pattern Recognition: Fine patterns inside an image get picked up, which is how the model handles objects whose shape and structure vary from one example to the next.
- Contextual Understanding: Training gives the model a sense of what an object means given everything around it. That context is what keeps recognition working in a busy, cluttered scene instead of only on clean single-subject photos.
Object Detection
Detection is where these models really show off. Break the image into its parts, then pin down exactly where each object sits and what it is. Several at once, in one pass.
- Bounding Box Prediction: Boxes drawn around objects give you their position, not just their presence, and position is what tells you how things in the scene relate to each other.
- Multi-Object Recognition: Many objects, one image, all detected and classified together. Real scenes are crowded, so this matters more than it sounds.
Image Captioning
Captioning is where vision crosses into language. The model looks at an image and writes a description of it, which requires understanding the picture rather than just labelling its contents.
- Semantic Description: The descriptions come out meaningful and fitted to context, which only happens if the model has grasped what the image is about.
- Multimodal Fusion: Visual and textual information get combined rather than handled in separate pipelines. Joining modalities this way is what makes an interaction with these systems feel closer to talking to a person.
Visual Question Answering
Ask a question about a picture, get an answer. That sounds simple and is not, because it requires the model to hold vision and language in the same thought.
- Contextual Reasoning: The answer gets worked out from the visual scene and the wording of the question together, which is a genuinely different kind of reasoning than classification.
- Multimodal Understanding: Because vision and language are joined, the model handles a wide spread of queries rather than a fixed set of question types.
Customization and Accessibility
Customization options and interfaces built for non-specialists have pulled large computer vision models out of the research lab. You no longer need a PhD to put one to work, and that shift has done more for adoption than any single architecture improvement.
- User-Friendly Interfaces: Platform like LandingLens™ provide an interface rather than an SDK, so someone with no coding background can build a custom large computer vision model.
- Accessible Training: Training a custom model is within reach now, which means teams can fit an AI solution to their own specific problem instead of bending the problem to fit a generic model.
Put it together and the picture is of a general-purpose tool rather than a specialist one. These models adapt, and that adaptability is why they keep showing up in problem domains nobody had them in mind for.
Applications of Large Vision Models
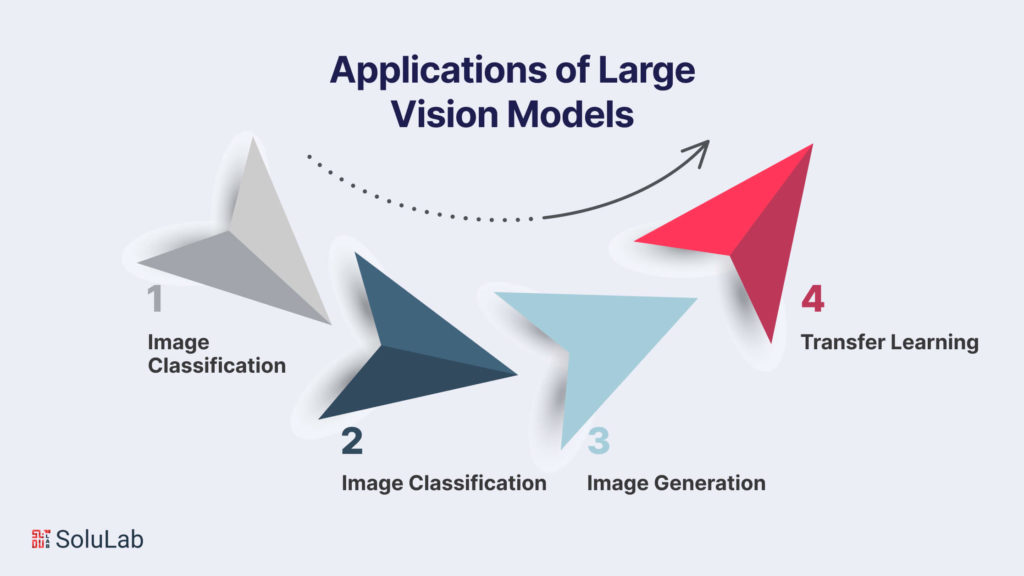
The applications have spread across industries and problem types, and they keep spreading, because reading visual information accurately turns out to be useful almost everywhere. Four applications are doing most of the heavy lifting right now. Here they are.
A. Image Classification
Classification came first and still does more work than anything else on this list. Most of these models rest on Convolutional Neural Networks, and they sort images across an enormous range of categories: objects, scenes, patterns that a person would struggle to name. Hospitals use it for medical image analysis. Factories use it for quality control. E-commerce sites use it so you can search by photo instead of by keyword. The common thread is machines approximating human visual judgment, at speed, on decisions that used to wait for a person to be available.
B. Object Detection
Detection means finding and outlining several objects inside an image or a video stream, and the range of places it turns up is wide. Surveillance systems use it to flag activity that looks wrong. Autonomous vehicles depend on it to read the road and respond to what is on it. Retail runs it on inventory and on automated checkout, which is the version most shoppers have actually stood in front of.
C. Image Generation
Generation flipped the direction of the whole field. Generative AI models, Generative Adversarial Networks among them, take what they learned from massive datasets and produce new images that look real. Creative arts, design, entertainment: that is where the demand sits. Artwork, synthetic visual content, assets that would otherwise cost a studio a week.
D. Transfer Learning
Transfer learning changed the economics. Knowledge learned on one task carries over to another, so a developer can start from a model pre-trained on a massive dataset and adapt it with a modest amount of labeled data. That is why it works across healthcare, finance, and natural language processing without a separate ground-up training run for each. Think of the pre-trained model as a store of visual understanding you borrow from rather than rebuild.
Across all four, the same thing is happening: machines are getting better at seeing, and what they do with what they see keeps widening. Expect the effect on industry and on ordinary life to get more pronounced, not less, as automation, decision support, and creative tooling all pull from the same well.
Challenges in Developing Large-Vision Models
None of this comes free. Large vision models have pushed AI a long way forward, and they have dragged a set of hard problems along with them. Three of those problems come up on almost every project.
A. Computational Resources
Building and training Large Language Models in AI are hungry. Millions of parameters, sometimes billions, and every one of them needs hardware behind it: GPUs, or Tensor Processing Units built for the purpose. For a small research group or a company without a budget line for this, getting access to that infrastructure is the wall they hit first. And the cost does not stop when training does. Deployment and inference keep drawing on the same resources, month after month.
B. Data Privacy and Ethical Concerns
Training data is the uncomfortable part. These models need enormous datasets, and enormous datasets tend to contain things people did not expect to hand over. Using that data responsibly is not optional. There is a second problem layered on top: whatever biases live in the training data get absorbed by the model without anyone deciding they should be. Holding both concerns at once, wanting varied data and protecting the people in it, takes real governance, written ethical guidelines, and a willingness to be transparent about what went into the model.
C. Bias and Fairness Issues
Bias does not go away on its own. A model learns from the data it is given, and if that data was not curated with care, existing bias gets reproduced and sometimes amplified. The output is discriminatory decisions, made at scale, by a system people assume is neutral. Fixing it takes work on three fronts: examining and curating the training data before it goes in, watching model outputs after deployment rather than at launch only, and using fairness-aware algorithms where they apply. This is an ethics question, obviously. It is also the reason anyone trusts an AI system enough to put it into production.
Teams that take these three seriously end up with better systems, not just more defensible ones. As the models keep getting bigger, treating the technical and the ethical work as the same job rather than two separate tracks is what decides whether the outcome is worth having.
Future Trends in Large Vision Models
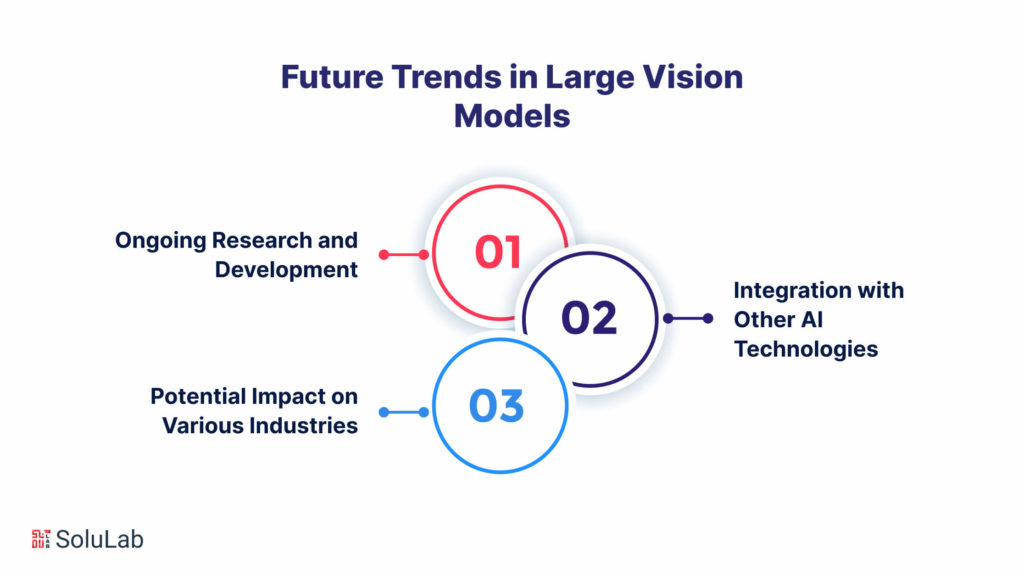
Where does this go next? The research pipeline suggests the technical gains will keep coming, and that the changes on the business side will be at least as significant.
A. Ongoing Research and Development
Research is moving on several fronts at once: new architectures, better optimization, different training methods. Three problems are getting the most attention, and they are the practical ones. Can we see why a model decided what it decided? Can we cut the compute requirement? Can we make training less energy-hungry? Alongside that, unsupervised and self-supervised learning are opening these models up to domains where labeled data barely exists, which is most domains.
B. Integration with Other AI Technologies
Combining large vision models with other branches of AI is where a lot of the near-term upside sits. Pair one with a natural language processing model and you get a system that reads and writes across both images and text. Pair one with reinforcement learning techniques and you get better decision-making in situations that keep changing while the system is trying to respond to them. Mixing disciplines this way produces systems that understand more of their own context, which is exactly what the single-purpose models were missing.
C. Potential Impact on Various Industries
Industry by industry, the effects look significant. Healthcare may see these models working across diagnostics, drug discovery, and personalized medicine, extending what clinicians can do rather than substituting for them. Manufacturing gets sharper quality control, fewer defects, better throughput. Retail gets recommendation systems that are actually useful and checkout that does not need a cashier. And autonomous vehicles get safer, which is the application where the stakes of getting it right are highest.
One theme runs under all of it: access. AI capability is reaching organizations that could never have built any of this themselves, and they are using it for decisions, automation, and products they could not have shipped before. Research keeps producing tools that are both more capable and easier to pick up, which is an unusual combination and a welcome one. As these models mature and fit more naturally alongside other AI technologies, they stop being a project and start being infrastructure, quietly making everyday tasks smarter and more specific to whoever is using them.
Conclusion
Large vision models have gone from research curiosity to something closer to standard equipment, and they have dragged the ethical questions about AI into the open along the way. They redefined what image classification means in practice. They forced conversations about training data that the field had been putting off. Calling them a tool undersells what has happened: the way teams approach visual problems is different now, and it is not going back.
If your organization is looking at this technology, the hard part is rarely the model itself. It is knowing which problem to point it at, what data you are allowed to use, and how to get it running somewhere other than a laptop. SoluLab, a well-known LLM development company, works with businesses on exactly that: scoping and building custom AI solutions, thinking through the ethical questions before they become incidents, and getting deployment right. SoluLab stays close to where this field is moving. Start with the problem, pick the model second, and you will be ahead of most teams attempting this.
FAQs
Shipra Garg is a tech-focused content strategist and copywriter specializing in Web3, blockchain, and artificial intelligence. She has worked with startups and enterprise teams to craft high-conversion content that bridges deep tech with business impact. Her work translates complex innovations into clear, credible, and engaging narratives that drive growth and build trust in emerging tech markets.