

Return on Investment (ROI) is basically the foundation of sound financial decisions in business. In plain terms, it measures how profitable an investment is by comparing what it returns, usually in dollars, against what it cost. Expressed as a percentage, ROI is one of the more useful metrics for judging whether a strategy, project, or initiative actually worked.
ROI = (Net Profit / Investment Cost) x 100
Understanding ROI matters because it tells you plainly whether an investment worked or not. Positive ROI means the investment brought in more than it cost; negative means the opposite. In short, ROI with machine learning helps businesses put resources where they’ll actually pay off.
Importance of Maximizing ROI
In a competitive market, how you allocate resources matters a lot. Maximizing ROI is really the key lever here. When businesses put money toward projects with stronger ROI potential, every dollar has a better shot at paying off, which compounds into more profit and steadier growth over time.
Maximizing ROI brings a few clear advantages:
- Resource Optimization: Businesses can put time, capital, and people where they’ll do the most good by focusing on higher-ROI initiatives.
- Risk Mitigation: Looking at potential ROI upfront helps businesses spot and manage risk before committing.
- Decision Clarity: ROI gives stakeholders a clear, objective number to weigh projects against, instead of relying on gut feel alone.
- Sustainable Growth: Keeping best ROI business practices in place drives growth that actually lasts.
Machine Learning’s Role
Machine learning, a subset of Artificial Intelligence, has become one of the more genuinely useful technologies of the last decade. It reads huge datasets, spots patterns, and makes predictions that hold up, which is why it’s showing up across industries as a way to boost Business ROI with Machine Learning.
It lets businesses make decisions grounded in data rather than guesswork, tighten up operations, and forecast market trends with real accuracy. That shows up in ROI directly: automating processes, sharpening customer experience, and surfacing revenue streams that weren’t obvious before.
Understanding Machine Learning
Machine learning is a branch of AI focused on building algorithms and models that let computers learn from data rather than run on hand-written rules. Where traditional programming spells out every instruction explicitly, machine learning algorithms pick up patterns and make predictions or decisions straight from data inputs. That capacity to learn from data is what makes it so versatile.
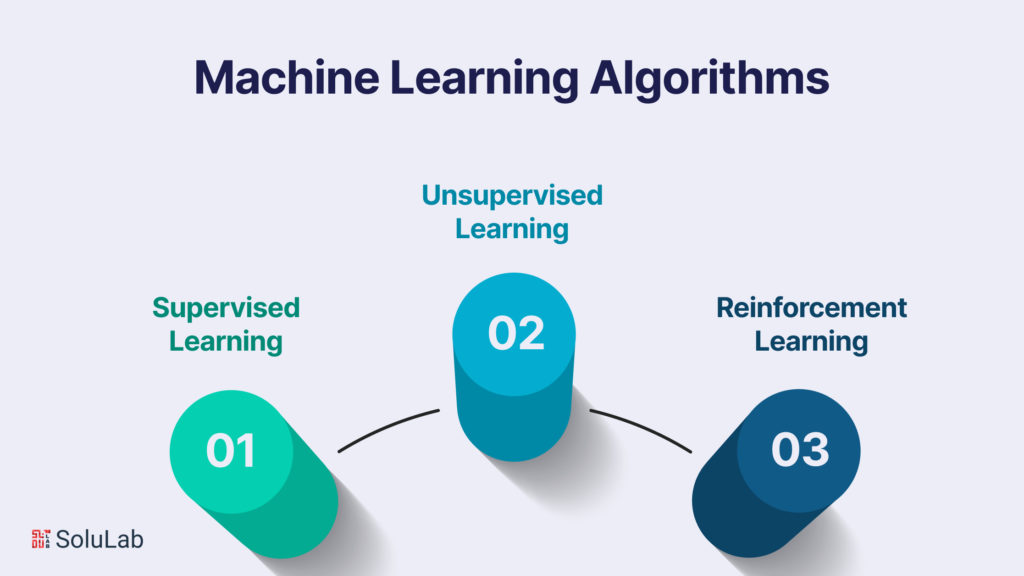
Machine learning algorithms generally fall into three categories:
- Supervised Learning: Trains on labeled data where the correct output is already known, so the algorithm learns to predict based on that labeling.
- Unsupervised Learning: Works with unlabeled data, hunting for patterns, clusters, or relationships without any explicit guidance.
- Reinforcement Learning: Trains algorithms to make sequential decisions by interacting with an environment, learning through trial and error, with rewards for good calls and penalties for bad ones.
Machine Learning’s Applications in Business
Machine learning shows up across business in ways that genuinely move the needle. A few examples:
- Customer Analytics: Helps businesses read customer behavior, predict preferences, and personalize marketing.
- Supply Chain Optimization: Predicts demand, trims inventory costs, and sharpens logistics.
- Fraud Detection: Financial institutions use it to catch fraudulent transactions in real time, protecting customers and the institution both.
- Predictive Maintenance: Manufacturing and aviation use it to predict when equipment needs servicing, cutting downtime and cost.
Data Gathering and Preprocessing
Before you get into models and strategies, it’s worth admitting the obvious: your data quality is what everything else rests on. “Garbage in, garbage out” isn’t a cliché here, it’s literal. Your model’s accuracy is only ever as good as the data it learned from.
High-quality data is:
- Accurate: Free from errors, duplicates, and inconsistencies, which is what makes the model’s insights trustworthy in the first place.
- Relevant: Tied directly to the problem you’re solving. Irrelevant data just adds noise and drags down performance.
- Complete: Missing data is a real roadblock. Completeness means the analysis has what it needs.
- Consistent: Structured uniformly so analysis holds together across data sources.
Collecting and Preparing Data
- Data Collection: How you collect data varies a lot depending on your business and industry: customer surveys, sensor data, website logs, whatever fits. What matters is building a reliable process that keeps data flowing in consistently.
- Data Preprocessing: Once you’ve got the data, it usually needs cleaning, transforming, and structuring before a model can use it. That means handling missing values, dealing with outliers, and encoding categorical variables.
- Feature Engineering: This is about building or selecting the features that actually help the model perform. It can make or break a project. In retail, for example, you might engineer features like purchase history or seasonal trends to sharpen sales predictions.
Data Quality
It’s hard to overstate how much data quality matters. Even the best algorithm can only work with what it’s fed. Careful gathering and preprocessing sets the foundation; skip it, and everything downstream suffers.
And it’s not a one-time job. As your business changes, so do your data needs. Regularly checking and maintaining data quality is what keeps your models delivering results you can trust.
Quality assurance here means fixing issues in historical data, sure, but also building processes that keep quality up going forward: data governance frameworks, validation checks, and clear ownership within your organization.
Put data quality first in your machine learning work, and you set yourself up for insights that actually drive ROI.
Choosing the Right Machine Learning Model
With quality data in place, it’s time to look at the algorithms themselves. These are the engines behind predictive analytics, turning raw data into useful insight. Different algorithms suit different jobs.
Some of the most common ones:
- Linear Regression: Predicts continuous numeric values, which fits tasks like sales forecasting or price prediction.
- Logistic Regression: Used for binary classification, customer churn prediction being a common example.
- Random Forest: An ensemble technique that handles both classification and regression well, and holds up on accuracy and robustness.
- K-Means Clustering: An unsupervised algorithm for grouping similar data points, useful for customer segmentation or spotting anomalies.
- Neural Networks: Deep learning networks, including CNNs and RNNs, excel at image recognition and natural language processing.
Selecting the Appropriate Model
The model you pick should line up with your specific ROI goal. For example:
- Regression Models: If you’re predicting a numeric value, customer lifetime value or product demand, say, linear regression or random forest regression tend to work well.
- Classification Models: For churn prediction or fraud detection, where you’re sorting data into categories, logistic regression or decision trees are solid choices.
- Clustering Models: If you want to segment your customer base for targeted marketing, K-means or hierarchical clustering can do the job.
- Deep Learning Models: For unstructured data, image analysis or natural language processing, deep learning models like CNNs and RNNs offer some of the strongest results available.
Complexity vs. Interpretability
Picking a model also means weighing complexity against interpretability. Deep neural networks, for instance, are often “black boxes”: hard to explain even when they perform well. That lack of transparency can be a real problem in regulated industries or anywhere interpretability matters.
Simpler models like linear regression or decision trees, on the other hand, are easier to read. You can look directly at coefficients or decision rules and understand why a prediction happened. The trade-off: they don’t always capture complex relationships as well as heavier models do.
Which way you lean should depend on your business needs and any regulatory constraints. Sometimes a hybrid approach, blending strengths from different models, ends up being the right call.
Training and Testing the Model
With good data in hand and a model picked out, next comes training. This is where the algorithm actually learns from the data to make predictions or decisions.
- Training Data: You need a dataset with both input features and known target values. The algorithm learns from this history, picking up patterns and relationships.
- Model Learning: During training, the model adjusts its internal parameters to close the gap between its predictions and the actual values. That’s what “optimization” or “learning” refers to here.
- Generalization: The whole point of training is getting the model to generalize to new data it hasn’t seen, not just memorize what it already has.
Data Splitting
To make sure a trained model actually generalizes, you split your dataset into two parts:
- Training Set: Roughly 70-80% of the data, used to train the model on patterns and relationships.
- Testing Set: The remaining 20-30%, kept aside for testing. The model hasn’t seen it during training, which makes it a fair check on how well the model generalizes.
Keeping training and testing data separate matters because it guards against overfitting, when a model learns the training data too well, picking up noise instead of real patterns. A model like that looks great on paper and falls apart on new data, because it’s essentially just memorized the training set.
Model Evaluation
Evaluating how well a model performs is a critical step, and which metrics you use depends on the problem type (classification, regression, and so on). Some common ones:
- Classification Metrics: For churn prediction or fraud detection: accuracy, precision, recall, F1-score, and ROC-AUC are all useful here.
- Regression Metrics: For regression tasks: Mean Absolute Error (MAE), Mean Squared Error (MSE), Root Mean Squared Error (RMSE), and R-squared (R²) all help gauge how well the model predicts numeric values.
You might also lean on cross-validation during evaluation, splitting the data into multiple subsets to get a more reliable read on performance.
And evaluation doesn’t stop once training’s done. It’s ongoing, since your business and data both keep changing. Re-evaluating and retraining regularly is what keeps predictions accurate and ROI gains sustained.
Implementing the Model in Your Business
Once your model is trained, the next hurdle is folding it into actual business operations, closing the gap between the data science and the day-to-day.
- Model Deployment: Deploying means making the model usable in real scenarios, whether that’s embedding it in a mobile app, a website, or an existing system.
- Scalability: Think about whether the deployed model can handle heavier loads and bigger datasets as your business grows.
- Automation: For real impact, push toward automation, letting the model make real-time predictions or decisions without someone stepping in manually.
Challenges and Solutions
Implementation tends to come with its own set of headaches:
- Data Drift: Incoming data can shift over time, which hurts model performance if you’re not watching for it. Build in monitoring to catch and adapt to drift.
- Model Monitoring: Keep watching performance in the real world. If it starts slipping, have retraining or alert mechanisms ready to trigger.
- Data Security and Privacy: Protect the sensitive data your model touches, and stay compliant with data protection rules to cut the risk of breaches.
Tackling these takes a mix of technical skill, data governance, and real collaboration between data scientists and business stakeholders.
Real-time Decision-Making
One of the bigger wins from putting machine learning into business operations is the ability to make real-time calls. Whether that’s personalizing product recommendations or fine-tuning inventory, real-time decisions can move ROI immediately.
Real-time decision-making powered by machine learning matters because it lets businesses respond fast to shifting conditions, adapt to what customers actually want, and grab opportunities as they come up.
Continuous Monitoring
Once a model is deployed, the work isn’t over, it’s really just starting. Real-world performance needs ongoing, active monitoring.
- Performance Metrics: Define the metrics that map to your business goals and check them regularly: accuracy, revenue generated, retention rates, or other relevant KPIs.
- Anomaly Detection: Build in anomaly detection to catch unusual patterns or deviations early, before they cost you revenue or customer trust.
- Feedback Loops: Set up feedback loops with the end-users or teams working with the model. Their observations often surface things the data alone misses.
Fine-Tuning Strategies
As your model runs in the real world, its performance will likely start to drift from your ROI goals at some point. That’s when fine-tuning becomes necessary.
- Retraining: Retrain periodically with updated data so the model keeps pace with changing conditions.
- Hyperparameter Tuning: Adjust things like learning rates or regularization strength to squeeze out better performance.
- Feature Engineering: Revisit your features periodically to make sure the model’s working with what’s actually predictive.
- Algorithm Selection: Sometimes a different algorithm or architecture just performs better as your business changes. Stay open to switching.
- Ensemble Methods: Ensemble methods, which blend predictions from multiple models, often boost both accuracy and robustness.
- Feedback Incorporation: Use feedback from end-users or domain experts to sharpen predictions. This loop tends to surface nuances the original build missed.
- Data Quality Control: Keep data quality standards tight. Drift, bad inputs, or shifting data sources can quietly wreck performance, so catch and fix issues fast.
Evolving Machine Learning Landscape
Machine learning keeps moving. New algorithms, tools, and techniques show up all the time, and staying current is what keeps your initiatives competitive.
- Continuous Learning: Push your data science and ML teams to keep learning: conferences, workshops, online courses, whatever keeps skills sharp.
- Experimentation: Stay open to trying new approaches and technologies to see if they beat what you’ve got for ROI.
- Collaboration: Bring data scientists, domain experts, and business stakeholders together. Mixing that expertise tends to produce better solutions than any one group alone.
- Ethical Considerations: Stay aware of bias and fairness issues. Make sure your models aren’t quietly reinforcing discrimination or inequity.
- Regulatory Compliance: Keep up with evolving data privacy regulations. Staying compliant protects you legally and keeps customer trust intact.
Concluding Remarks
Monitoring and fine-tuning your model isn’t a one-off task, it’s an ongoing process. Keep assessing and improving performance, and it’ll keep paying off in ROI and business results.
SoluLab builds software with a focus on technologies like machine learning. We help businesses turn data into decisions that actually move profitability, which is really the whole point of this guide. With deep experience in machine learning development services, SoluLab is a solid partner for driving ROI through practical, current solutions.
Partner with SoluLab to put their machine learning expertise to work and push your business further.
FAQs
Shipra Garg is a tech-focused content strategist and copywriter specializing in Web3, blockchain, and artificial intelligence. She has worked with startups and enterprise teams to craft high-conversion content that bridges deep tech with business impact. Her work translates complex innovations into clear, credible, and engaging narratives that drive growth and build trust in emerging tech markets.