

Two techniques keep coming up when a language model needs to answer accurately about your specific domain: Retrieval-Augmented Generation (RAG) and fine-tuning. Different tools. Same goal.
Here’s the core split. RAG lets an LLM reach into an outside knowledge source and pull relevant facts at the moment of the question, then answers with that context in hand.
Fine-tuning works from the other direction. You keep training the model on a focused dataset until it picks up the vocabulary, the patterns, and the behavior a specific industry or task actually needs.
So which one fits your project? This piece walks through where RAG and fine-tuning differ, when each earns its keep, what you give up with either, and how to pick the right one when you’re building reliable AI applications.
Key Takeaways
- The Problem: Plenty of teams get stuck picking between RAG and fine-tuning, and the wrong call shows up fast. You end up with stale answers, a training bill you didn’t plan for, or a model that ignores your own company data.
- The Solution: RAG sharpens answers by fetching live external knowledge. Fine-tuning teaches the model on your own labeled data. Which one wins comes down to what data you have, what you can spend, and how often the facts change.
- How SoluLab Helps: SoluLab, with the help of AI, helps businesses design enterprise AI systems using RAG, fine-tuned LLMs, or hybrid architectures. Our team builds scalable AI solutions that integrate private data, improve accuracy, and deliver reliable AI
What is the difference between RAG and Fine-Tuning?
Think of it this way. RAG sends the AI to look things up before it answers, pulling from sources outside the model. Fine-tuning skips the lookup and instead trains the AI on specialized data so it gets sharper at the task itself. One adds knowledge from the side. The other rebuilds the model from within.
And the numbers back the distinction up. One comparative study reported RAG systems beating fine-tuned models by as much as 16% in ROUGE scores and 15% in BLEU scores. Let’s take each one apart:
What is Retrieval-Augmented Generation?
Retrieval-Augmented Generation (RAG) is a framework Meta introduced back in 2020. The idea: wire a large language model up to a curated, changing database so it can answer with current, trustworthy facts instead of whatever it memorized during training. The payoff shows up as better accuracy and sharper reasoning in context.
Key Components of RAG Development
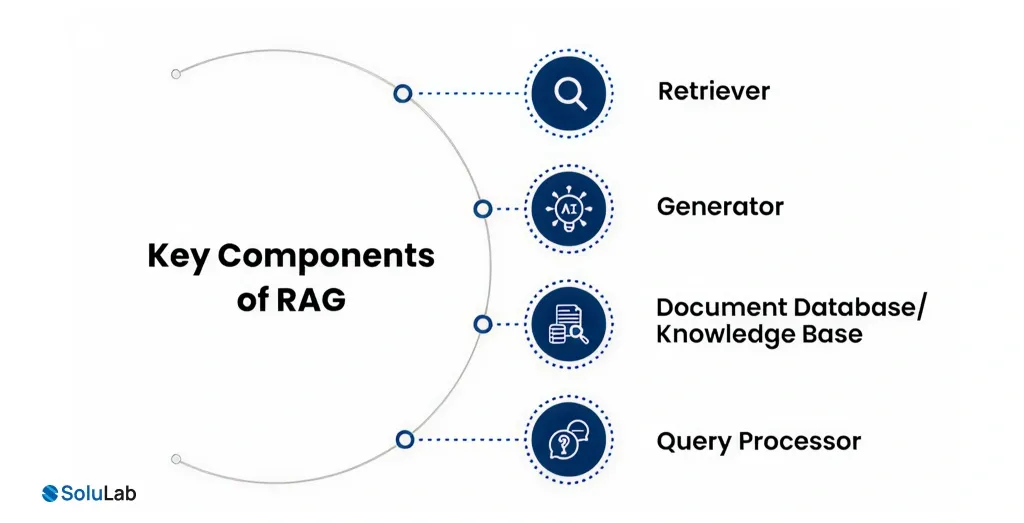
A RAG architecture has a lot of moving parts, and getting it right means stitching several tools together. You’re looking at prompt engineering, a vector database like Pinecone, embedding vectors, semantic layers, data modeling, and the pipelines that move data between all of it. Every piece gets tuned to what the specific system needs.
Here are the main components of RAG development, in plain terms:
1. Retriever: This is the part that digs through a knowledge base, documents, databases, whatever you’ve indexed, and surfaces the bits that match the user’s question. Call it the AI’s research assistant.
2. Knowledge Base / Vector Store: Your documents and data, chunked and stored so search stays fast and accurate. Usually that means embeddings living in a vector database like Pinecone or FAISS.
3. Embedding Model: Turns both the query and your documents into vectors, numbers, basically, so the system can measure which ones actually match. OpenAI’s embeddings and Sentence Transformers are common picks.
4. Generator (LLM): The big model, GPT-4 for example, reads the retrieved documents and writes back an answer that sounds human and stays grounded in what was actually retrieved.
5. Orchestration Layer: This runs the whole show, from the moment a query lands through retrieval and on to generation. LangChain and LlamaIndex are the tools most developers reach for to keep that flow tidy.
How Does RAG Work?
1. Query Processing: It all kicks off when a user asks something. That question is the trigger for everything the retrieval side does next.
2. Data Retrieval: Now the system goes hunting. Working from the query, it searches its database for the material that fits, using retrieval algorithms to pull the most relevant, most contextually aligned data it can find.
3. Integration with the LLM: What came back gets bundled together with the original question and handed to the LLM. That gives the model a rich, grounded starting point instead of a blank slate.
4. Response Generation: With the context and the question in front of it, the LLM writes the final answer, one that’s accurate and shaped to exactly what was asked.
What is Fine-Tuning?
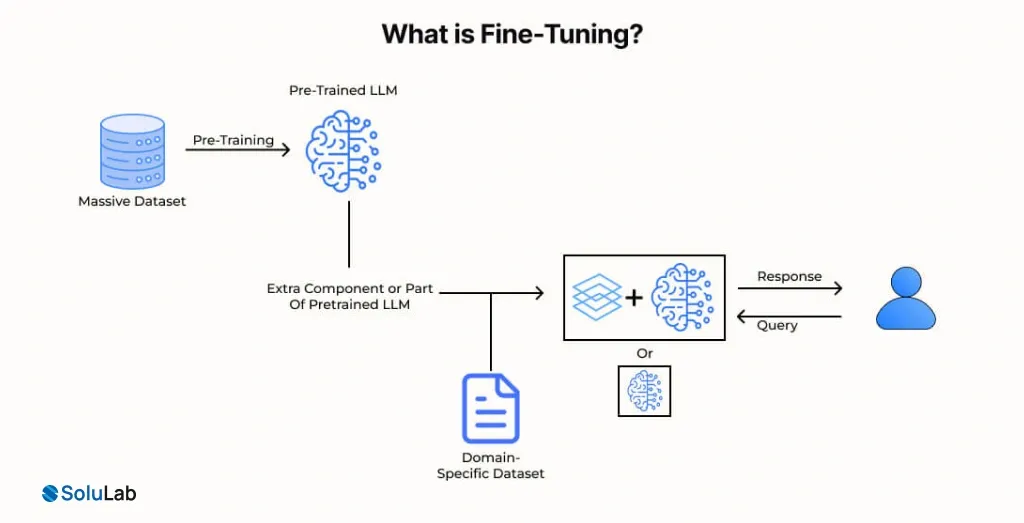
Fine-tuning takes a different road to building generative AI. Here you train the LLM on a smaller, labeled, purpose-built dataset, adjusting the model’s parameters and embeddings so it actually adapts to that new data rather than just referencing it.
- Place the image here
For enterprise-ready AI, RAG and fine-tuning are chasing the same prize: squeezing real business value out of AI models. They just get there differently. RAG hands the LLM a key to a proprietary database. Fine-tuning goes deeper and reshapes the model itself around one domain.
The work happens by training the LLM on a niche, labeled dataset, one that carries the specific terms and subtleties of a given field. Do that well and the model handles specialized tasks far better, which is exactly why fine-tuning suits domain-specific work.
Types of Fine-Tuning for LLMs
Fine-tuning large language models (LLMs) isn’t a single recipe. There are several approaches, and each one answers to different goals, data sizes, and budgets. Here are the main ones:
1. Supervised Adjustment
You take a model that’s already trained and keep training it, this time on a task-specific dataset of labeled input-output pairs. The model learns, example by example, how to map an input to the right output using the data you gave it.
How it works:
- Start from a trained model.
- Build a dataset of input-output pairs that matches what the model needs to learn.
- As you fine-tune, update the pre-trained weights so the model settles into the new task.
Got labeled data? Supervised fine-tuning is a natural fit for jobs like named entity recognition, text classification, and sentiment analysis.
2. Instructional Adjustment
Here the prompt template carries detailed guidance alongside the input-output examples. That extra instruction helps the model stretch to new tasks, especially the ones spelled out in everyday language.
How it works:
- Start from a trained model.
- Put together a dataset of instruction-response pairs.
- Train the model through the instruction fine-tuning routine, much like standard neural network training.
Chatbots, question-answering systems, anything that leans on back-and-forth natural language, these lean on instruction fine-tuning a lot.
3. PEFT, or parameter-efficient fine-tuning
Training a whole model eats resources. PEFT gets around that by touching only a slice of the model’s parameters, which cuts the memory bill and keeps both memory and compute in check.
PEFT Techniques:
- Selective Method: Freeze most of the model’s layers and fine-tune only a handful.
- LoRA, or the Reparameterization Method: Freeze the original weights and reparameterize them by bolting on tiny trainable low-rank matrices.
Picture a model sized 512 by 64. Full fine-tuning would demand 32,768 parameters. LoRA drops that to 4,608. Big difference.
- Additive Method: Train fresh layers on the encoder or decoder side for the task at hand, instead of touching what’s already there.
- Soft Prompting: Add new tokens to the model prompt and train only those, leaving every other token and weight frozen.
The upshot: PEFT trims training costs and resource demands, which really matters once your models get big enough to bump against memory limits.
4. Human Feedback Reinforcement Learning (RLHF)
RLHF brings reinforcement learning in to line the refined model’s output up with what people actually prefer. It runs after the first fine-tuning pass and polishes how the model behaves.
How it works:
- Prepare Dataset: Build prompt-completion pairs and have human reviewers rank them against your alignment standards.
- Train Reward Model: Turn that human feedback into a reward model that can score completions on its own.
- Revise the Model: Use reinforcement learning, typically the PPO algorithm, to update the model’s weights against the reward model.
When you need outputs that read as genuinely human, say, language that respects ethical lines or user expectations, RLHF is the one to reach for.
How Fine-Tuning Works?
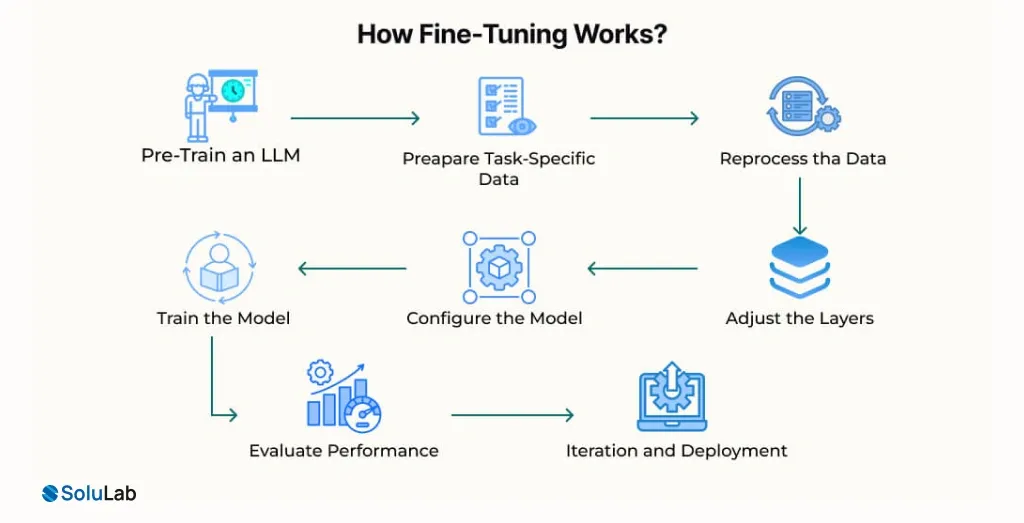
If you want a general LLM to do one job well, fine-tuning is the step that gets you there. Here’s how the process plays out, geared toward anyone new to fine-tuning RAG.
1. Start with a Pre-Trained Model: Begin with a model that already knows the basics of language and how words relate. Fine-tuning is what bends that broad knowledge toward one specific task and makes it more accurate at it.
2. Collect Task-Specific Data: Pull together a smaller dataset tied to your task, customer queries, product details, whatever fits. Then split it into training, validation, and testing sets so you can actually judge performance.
3. Clean and Prepare the Data: Comb through for errors, duplicates, and half-finished entries, and clear them out. Clean, well-structured data is what lets the model learn properly and hand back results you can trust.
4. Adjust Model Layers: A pre-trained model processes information across many layers. During fine-tuning you usually update only the top ones, so the model learns the new task without forgetting the language knowledge it already holds.
5. Configure Training Settings: Dial in the parameters that matter, learning rate, batch size, how many training cycles you’ll run. These decide how quickly and how well the model absorbs the new data.
6. Train the Model: Feed the prepared data in and let the model pick up the patterns behind your task. As it trains, it keeps adjusting its answers to cut errors and lift accuracy.
7. Evaluate Model Performance: Put the model up against new, unseen data to see how it holds. Lean on evaluation metrics, human feedback, or both to gauge whether the answers are accurate and genuinely useful.
8. Improve and Deploy the Model: Not quite there? Loop back and retrain with better data or settings. Once the results hold up, ship the model into real applications and put it to work
Differences Between RAG and LLM Fine-Tuning
The table below lays out where LLM RAG and Fine-Tuning part ways, so you can see when each one is the right call. Both improve large language models. How they do it, and where they shine, is another story.
| Aspect | RAG (Retrieval-Augmented Generation) | LLM Fine-Tuning |
| Objective | Augment responses with external retrieved data at inference time for factual accuracy and freshness | Adapt model weights during training for specialized behavior, style, or domain expertise |
| Data Dependency | Relies on external knowledge base (e.g., vector database) that must be indexed and maintained | Requires labeled training dataset specific to the task |
| Training Effort | Minimal; no model retraining, just setup retrieval pipeline | High; compute-intensive training process, often thousands to hundreds |
| Knowledge Update | Dynamic and real-time via updated external sources, no retraining needed | Static post-training; requires full retraining for updates |
| Inference Cost | Higher per query due to retrieval step adding latency and compute | Lower; fast inference after one-time training |
| Customization Level | Moderate; flexible context injection but limited style/behavior changes | High; deep adaptation of tone, terminology, and reasoning |
| Best For | Enterprise support agents, researchers, journalists | Domain specialists (finance, healthcare, legal), automation engineers |
| Examples | Chatbots with enterprise docs, news summarization | Sentiment analysis in finance, medical diagnosis tuning |
Build Enterprise AI Systems with SoluLab
SoluLab builds scalable AI systems for enterprises that automate workflows, pull insight out of data, and back sharper decisions, all on top of advanced machine learning, LLMs, and enterprise-grade AI architectures.
We put AI to work to move faster and smarter, and that means quicker deliverables without blowing the budget. Here’s what we can build with you:
Services
- Custom large language model development
- Retrieval-augmented generation (RAG) implementation
- Enterprise AI knowledge assistant development
Intelligent AI chatbot development solutions
Case Study
SoluLab worked with InfuseNet, an AI platform that lets businesses bring in and connect data from text, images, documents, and APIs to build smart, personalized applications.
At its heart is a drag-and-drop interface wired to advanced models like GPT-4 and GPT-NeoX. Teams use it to spin up ChatGPT-style apps on their own private business data, without letting security or day-to-day efficiency slip.
Because it plugs into services like MySQL, Google Cloud, and CRM platforms, InfuseNet lets organizations build data-driven apps that lift productivity, tidy up workflows, and feed better business decisions.
Conclusion
RAG and fine-tuning both get you to more accurate, domain-aware AI. The right pick just depends on what you’re optimizing for.
Chasing knowledge retrieval and lower upkeep? RAG usually wins. Need deeply tailored answers and real specialist depth? That’s fine-tuning’s territory.
In the end it comes down to your data, your use case, and how far you plan to scale. SoluLab, an LLM development company, can help you design and stand up the AI architecture that holds up over the long haul.
FAQs
Shipra Garg is a tech-focused content strategist and copywriter specializing in Web3, blockchain, and artificial intelligence. She has worked with startups and enterprise teams to craft high-conversion content that bridges deep tech with business impact. Her work translates complex innovations into clear, credible, and engaging narratives that drive growth and build trust in emerging tech markets.