

A general-purpose language model knows a little about everything. That’s the problem. Ask it about a niche, whether that’s credit risk, clinical notes, or contract clauses, and it answers with the confidence of someone who skimmed the Wikipedia page. Fine-tuning a GPT model is how you close that gap. You take a capable base model and teach it the language of one field, so the text it produces is relevant, accurate, and fits the context your readers actually live in. Finance, healthcare, law, or something far more obscure: the principle holds.
The mechanics are simple to describe. You train the model on data from your domain until it picks up the vocabulary, the habits, and the small distinctions an outsider would miss. Doing it well is harder. This guide walks through ChatGPT fine-tuning step by step, from picking data to choosing a model variant to checking whether the result is any good, so you can build a model that sounds like it belongs in your field.
Read Also: What is GPT?
What are the Advantages of the ChatGPT Fine-tuning analytics model?
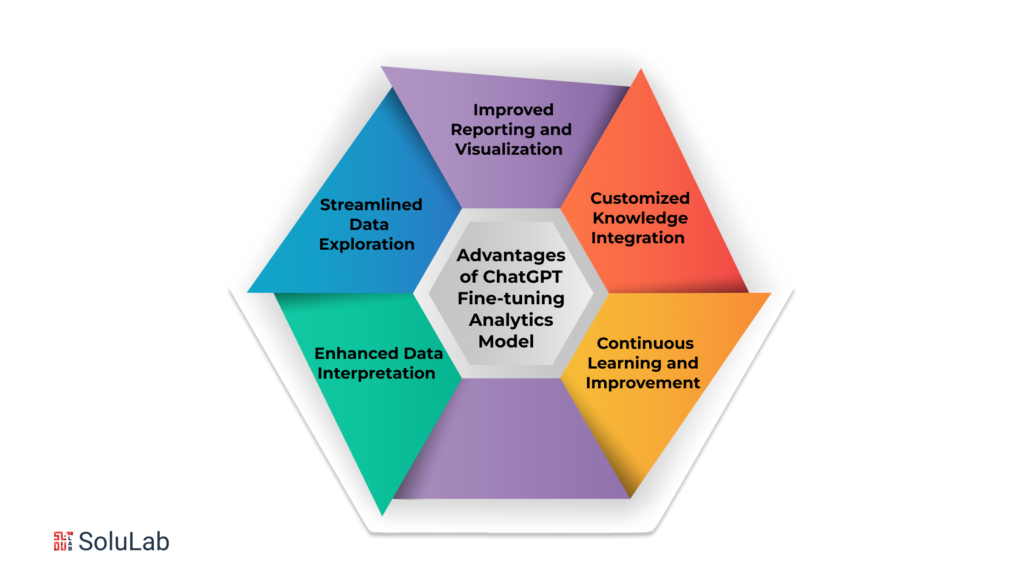
Analytics is one of the clearest cases for fine-tuning. A model that understands how analysts talk, and what they mean by a “cohort” or a “lift,” stops being a toy and starts pulling its weight. So what do you actually get out of it? Here’s the short list.
Enhanced Data Interpretation
A fine-tuned model can follow analysis terminology, statistical concepts, and the jargon specific to your business. That means its readings of complex data sets are sharper and more useful. Analysts get to the meaningful conclusion faster.
Spotting a pattern, flagging a trend, explaining why two variables move together: a fine-tuned ChatGPT model can handle all of it and quickly becomes the assistant nobody on the analytics team wants to give back.
Streamlined Data Exploration
Big data sets mean poking at lots of variables, dimensions, and relationships. It’s slow. A fine-tuned GPT model can be trained to understand the kinds of exploratory questions your analysts ask, and to return quick, relevant answers.
Instead of writing yet another query, an analyst just asks. The model replies right away, and that back-and-forth helps with exploration, testing a hypothesis, or deciding what to do next.
Improved Reporting and Visualization
Writing thorough reports and building charts that really communicate a finding eats hours. But a fine-tuned ChatGPT model can take on a good chunk of that work.
It can describe what the analysis found, summarize the key points, and suggest which chart fits the story. Reporting speeds up. Analysts get time back for the strategic thinking they were hired to do.
Read Our Blog: Top 10 ChatGPT Development Companies
Customized Knowledge Integration
Fine-tuning for analytics lets you build your own domain knowledge into how the model thinks. Train it on data from a specific industry or business line, and its insights and recommendations start to fit your situation instead of some generic average.
Finance, marketing, healthcare, any field that runs on numbers. A fine-tuned ChatGPT model draws on the right expertise and gives answers that are more accurate and better suited to the context.
Continuous Learning and Improvement
A fine-tuned model isn’t frozen. As new data arrives or your field shifts, you can update and refine it, and each round keeps it current with the latest trends and sharpens its performance.
Run ChatGPT fine-tuning on a regular schedule and you end up with a model that moves with your data, not one that quietly goes stale while your decisions keep depending on it.
How to Fine-tune GPT Models for Specific Domains?
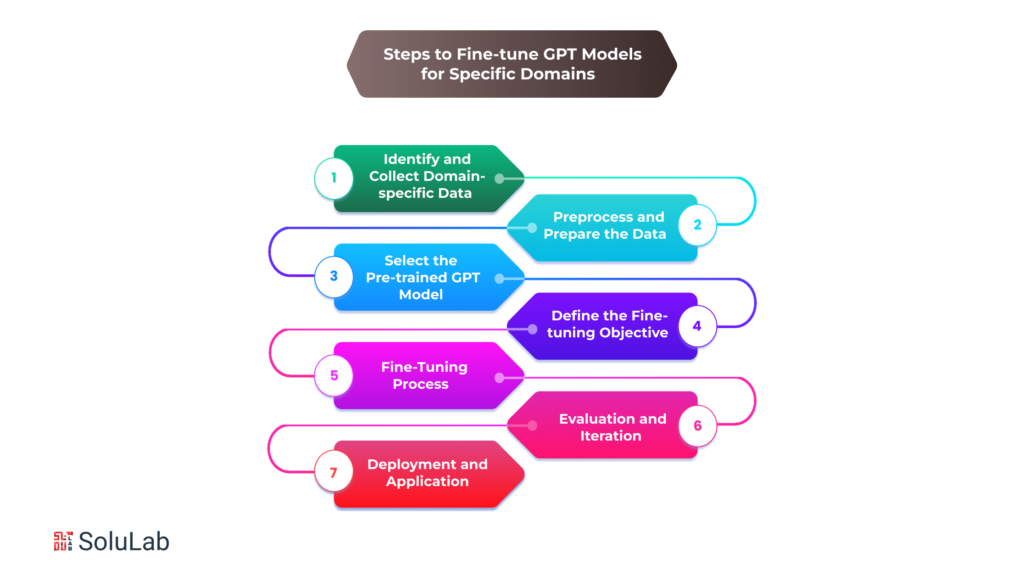
Fine-tuning for a specific domain is how you point a general model at your actual problem. Feed it data from your field and it gets better at producing content that is accurate and relevant there. Below is the process, one step at a time, for getting a GPT model to perform well in the domain you care about.
1. Identify and Collect Domain-specific Data
Start with data. You need a dataset built from your target domain: text samples, documents, and any other sources that carry the language and context of the field. Variety matters more than people expect. If your dataset only covers the easy, common cases, the model will only learn those, so make sure it spans the full range of topics and situations your domain throws at you.
2. Preprocess and Prepare the Data
Raw data is messy. Before any of it goes near training, clean it: strip out irrelevant or noisy records, fix inconsistencies, and get the text into one standard format. You may also need to annotate it with labels or tags so the model can tell which tasks or intents matter in your domain. In practice, this is where teams get stuck, and it’s also where a lot of the final quality gets decided.
3. Select the Pre-trained GPT Model
Next, pick your starting point. There are several pre-trained options, such as GPT-3, GPT-2, or the newer GPT-4. Weigh the model’s size, how it performs on general language tasks, and whether it supports the fine-tuning approach you plan to use. Get the base model wrong and no amount of clever training will fully rescue you.
4. Define the Fine-tuning Objective
What exactly should the model be good at? Decide before you train. It might be text generation, sentiment analysis, question answering, or some other task tied to your use case. A clear objective gives the whole fine-tuning process a target, and the model’s performance gets tuned toward that one job.
Read Our Blog: How Does ChatGPT Help Custom Software Development?
5. Fine-tuning Process
Now the actual training: you run the chosen pre-trained model over your domain dataset. The trick is balance. Underfit, and the model never picks up the nuances of your field. Overfit, and it memorizes the training data and falls apart on anything new.
Expect to lean on gradient-based optimization, adjust learning rates, and apply regularization along the way. Then experiment. Try different hyperparameters, batch sizes, and numbers of training epochs until you find the setting that suits your domain, because there is rarely a universal right answer here.
6. Evaluation and Iteration
Once training finishes, test the model on a separate validation dataset, or with other metrics that make sense for your domain. Ask three questions. Does it do the intended task well? Does it handle the nuances of the domain’s language? Are its outputs accurate and appropriate to the context?
The answers usually send you back for another pass. Maybe you tweak hyperparameters, collect more data, or try a different pre-trained model. That loop is the point. Each round brings the model closer to what your domain actually demands.
7. Deployment and Application
Happy with the results? Then ship it into your production systems or applications. Check that your infrastructure can carry the model’s compute load and that it fits cleanly into the workflow people already use. After launch, keep watching. Track performance, listen to user feedback, and note where the model needs further work or adaptation.
How to Choose the Appropriate Fine-tune GPT-3 Model Variant for Fine-tuning?
Picking the right GPT-3 variant is one of the decisions that shapes everything after it. The GPT-3 family comes in several variants with different sizes and capabilities, each suited to different use cases and compute budgets. Choose badly and you either overpay for power you don’t need or underpower a hard task. These are the factors worth weighing:
Model Size and Computational Resources
GPT-3 models range widely in size, from a few million to hundreds of billions of parameters. Size drives two things: how much compute the model needs, and how well it can capture complex relationships in your data. If you’re working with limited hardware, like CPUs or low-memory setups, a smaller model is often the sensible pick. Larger models, on the other hand, cope with bigger and more varied datasets and give more nuanced output.
Fine-tuning Objective
Go back to your objective. Do you need coherent, context-aware responses, or are you pulling detailed information out of text? Simple tasks can often get by with a smaller GPT-3 variant. Harder ones may need a larger model with more parameters to pick up subtle distinctions and perform well.
Domain Expertise and Vocabulary
Some GPT-3 variants are trained on specific domains, such as legal or medical texts, and handle language in those fields better [SOURCE NEEDED]. If your project centers on one domain, a variant already aligned with it gives you a head start on the relevant knowledge and the specialized vocabulary.
Latency and Response Time
Bigger models are slower. The size of a fine-tuned model sets how long inference takes, and larger ones generally respond more slowly because they need more compute. So check your application’s latency limits up front, since a sluggish reply can hurt the user experience and overall performance more than a slightly less clever answer would.
Data Availability and Task Complexity
How much domain data do you really have? Larger models usually need more training data to generalize well. With a small dataset, a smaller GPT-3 variant is often the safer choice because it’s less likely to overfit. With plenty of varied data, a larger variant can pick up a broader range of patterns and nuances.
Experimentation and Evaluation
When in doubt, test. Try several GPT-3 variants on your actual task and compare them on text quality, coherence, and relevance to your domain. Evidence from your own data beats any rule of thumb, and it makes the final call much easier to defend.
How to Evaluate the Performance and Quality of the Fine-tuned Model?
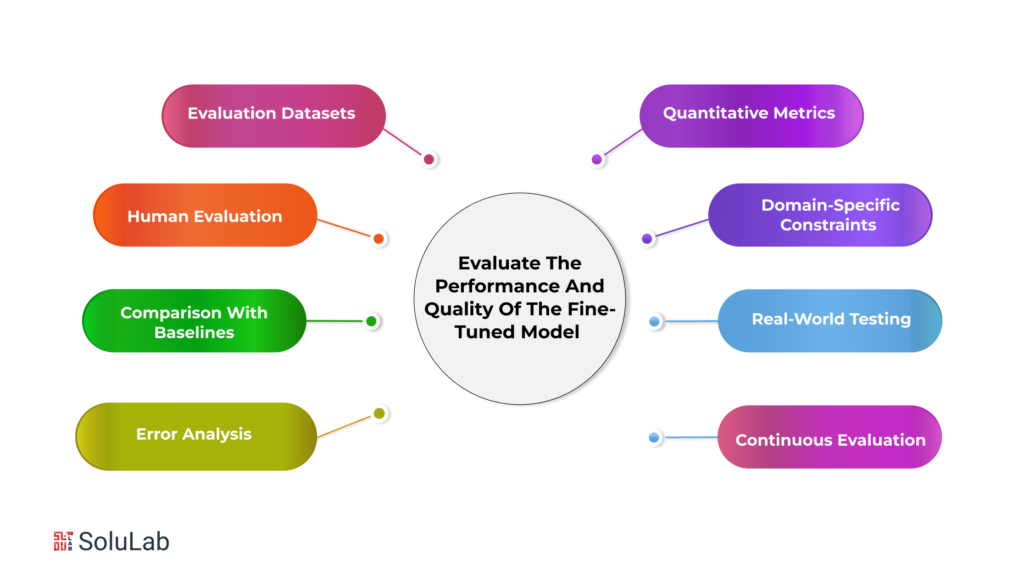
A model that trained without errors is not the same as a model that works. Evaluation tells you whether it’s effective and whether it’s ready to deploy. Here are the strategies and metrics that matter:
Evaluation Datasets
Keep evaluation data separate from training data. Always. These sets should cover a wide spread of scenarios and use cases in your domain, and they should mirror the distribution and characteristics of the real-world data the model will meet once it’s deployed.
Quantitative Metrics
Put numbers on performance. Common choices are accuracy, precision, recall, F1 score, perplexity, or whatever domain-specific metric fits your task. Numbers are objective, and they point straight at the areas that need work.
Human Evaluation
Metrics miss things people notice instantly. So bring in human reviewers who know your domain and give them a standard evaluation protocol. Hand them clear criteria for judging the model’s responses, such as relevance, fluency, and coherence. Their judgment fills in the subjective side of performance that no score quite captures.
Domain-specific Constraints
Every field has its own rules. Check how well the model respects them. In legal or medical work, for instance, following regulations and ethical guidelines may be non-negotiable. Make sure the model’s outputs stay within those limits and don’t produce biased or sensitive content.
Comparison with Baselines
Is the fine-tuned model actually better than what you had? Set baselines by comparing it against existing models or methods in your domain. That gives you a benchmark and shows how much fine-tuning really bought you. Run proper statistical tests to confirm whether any difference is significant or just noise.
Real-world Testing
Put the model inside real applications or workflows and see what happens. Collect feedback from the users and domain experts working with it day to day. Their experience tells you a lot about its effectiveness, usability, and performance outside the lab.
Error Analysis
Dig into the mistakes. A careful error analysis shows where the model is weak and where it hits its limits. Look for recurring errors and failure cases, then trace the patterns or causes behind them. What you find becomes the plan for the next round of fine-tuning.
Continuous Evaluation
Deployment isn’t the finish line. Keep evaluating and monitoring the model afterward: gather user feedback, track your performance metrics, and stay alert to how your domain’s needs and challenges change. That’s what lets you keep improving it and keep it useful over time.
Conclusion
A GPT model fine-tuned for a niche stops sounding like a tourist. It learns the details of a specialized industry or body of knowledge by training on that field’s own data, and it picks up the nuance and context it needs to produce content that is accurate and relevant.
Where do you start? With data sources from your domain. Think domain-specific datasets, research papers, online forums, and the subject matter experts who know things no dataset records.
With the data in hand, configure the model and set your fine-tuning objectives. Choose the GPT variant carefully, weighing model size, available compute, and how hard the task really is. Configuration means setting up the architecture and hyperparameters for your domain. And training techniques such as gradual unfreezing or learning rate scheduling can squeeze out further gains in performance.
SoluLab has an experienced, skilled team that builds custom ChatGPT clones shaped around each client’s business requirements. As a leading ChatGPT applications development company, SoluLab keeps sharpening its expertise and updating its services with the latest technology, with the goal of giving businesses capable AI chatbot solutions. The team covers integration, development, fine-tuning, and maintenance of custom AI solutions, and it draws on hands-on experience in ML, NLP, and Deep Learning to build engaging OpenAI experiences. If you want to see the difference for yourself, hire SoluLab’s top ChatGPT developers for your AI development needs.
ChatGPT is only part of it. SoluLab’s Generative AI development services also offer models and solutions inspired by ChatGPT, DALL-E, and Midjurney. Its generative AI specialists work across a wide range of AI technologies and help businesses use these tools to produce custom, high-quality content that stands out from competitors. Looking for state-of-the-art generative AI development services built around your company’s requirements? SoluLab is a good place to look. Get in touch today to find out how the team can raise your company’s technical capabilities with advanced AI solutions.
FAQs
Shipra Garg is a tech-focused content strategist and copywriter specializing in Web3, blockchain, and artificial intelligence. She has worked with startups and enterprise teams to craft high-conversion content that bridges deep tech with business impact. Her work translates complex innovations into clear, credible, and engaging narratives that drive growth and build trust in emerging tech markets.